Direct answer
Twilio voice incidents Thailand France carrier maintenance October 2026 post dial delay: what buyers need to know
Twilio's public status page showed current and recent October voice incidents, including carrier maintenance affecting voice traffic to France and a Thailand voice issue involving post-dial delay or audio quality. Third-party incident tracking also mirrored recent Twilio voice status activity. For VoIP buyers, the practical lesson is not that one provider outage proves a stack is weak. It is that production call paths need route-specific failover evidence: affected geography, call symptom, alternate carrier or callback path, customer notice owner, planned maintenance handling and post-incident retest proof.
This brief cites the source announcement and translates the event into a buyer framework. Verify current vendor terms before changing phone, messaging, or AI routing.
What happened
- Twilio's status page listed planned carrier maintenance affecting voice traffic to France with a defined maintenance window.
- The same public status history listed a Thailand voice incident involving post-dial delay and possible degraded audio quality.
- Independent status-tracking pages mirrored Twilio incident activity, which helps confirm this was not merely a private customer note.
- This article treats the incidents as a buyer diligence trigger, not as a finding about any customer's contract, SLA or final root cause.
Why this is trending
- Cloud voice buyers often depend on CPaaS and carrier layers that expose route symptoms by country, carrier partner or number group.
- Post-dial delay, audio quality degradation and planned carrier maintenance can all become customer-facing support issues even when the core application is healthy.
- This is distinct from recent RMD and MVNO filing coverage because the buyer asset focuses on operational failover evidence for provider and carrier route incidents.
The VoIP Stack Index take
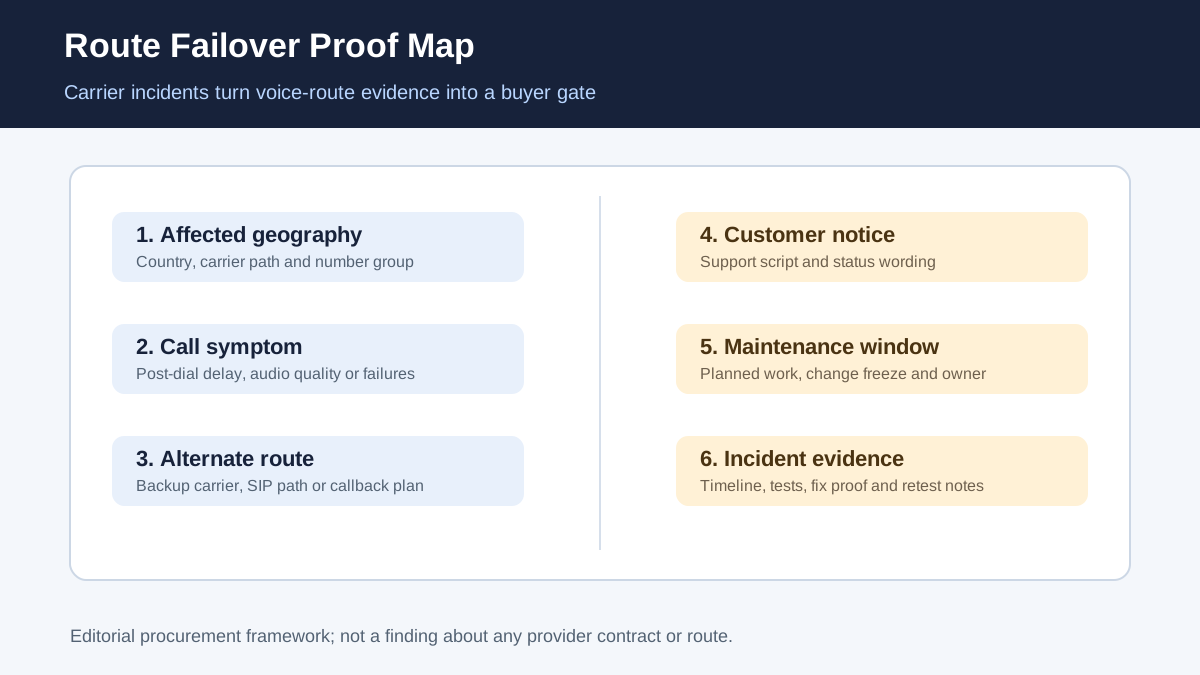
Consider an illustrative business using a CPaaS provider for appointment reminders, support callbacks and international customer calls. A country-specific carrier incident may not break every call, but it can still create long post-dial delays, poor audio, abandoned calls or support confusion. Before relying on one voice route, buyers should know which geographies are critical, what symptoms trigger failover, which alternate route is approved, who tells customers and how retesting closes the incident. This framework is an editorial procurement aid, not legal advice or a provider-performance finding.
Route Failover Proof Map
An original buyer map for affected geography, call symptom, alternate route, customer notice, maintenance window and post-incident evidence.
What buyers should do next
Map critical call flows by country, carrier path, number inventory and customer-impact tolerance.
Define symptom thresholds for post-dial delay, audio degradation, failed setup and callback failure.
Keep a tested alternate route for high-value or safety-sensitive calls before the next carrier incident.
Prepare support wording for planned maintenance and unplanned route degradation.
Retain call IDs, timestamps, route evidence and retest notes after the provider marks an incident resolved.
Buyer bridge
Do the routing audit before buying the buzz.
The winning AI phone stack is the one that preserves context, controls fallback, and lets humans take over without making the customer repeat the story.
Run the AI-ready VoIP audit